<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://zephyr4772.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://zephyr4772.github.io/" rel="alternate" type="text/html" /><updated>2026-10-26T14:23:57+00:00</updated><id>https://zephyr4772.github.io/feed.xml</id><title type="html">Sinhal Joshi</title><subtitle>Notes on evaluating AI systems, mostly where models fail.</subtitle><author><name>Sinhal Joshi</name></author><entry><title type="html">A 2019 classifier ties a 2026 decision model on agent guardrails</title><link href="https://zephyr4772.github.io/2019-classifier-ties-2026-decision-model/" rel="alternate" type="text/html" title="A 2019 classifier ties a 2026 decision model on agent guardrails" /><published>2026-10-26T00:00:00+00:00</published><updated>2026-10-26T00:00:00+00:00</updated><id>https://zephyr4772.github.io/2019-classifier-ties-2026-decision-model</id><content type="html" xml:base="https://zephyr4772.github.io/2019-classifier-ties-2026-decision-model/"><![CDATA[<p>In September 2026, TypeSafe AI launched <strong>Jev</strong>, a “decision model”. You give it a task and a question with a fixed set of options, and it returns typed answers (a choice, a score, a yes/no), each with a probability, in a single pass. Vercel added it to its AI Gateway and called it the fastest-adopted model in the gateway’s history. The open-source <strong>Laya</strong> works the same way.</p>

<p>The pitch is that this claimed to be a new kind of model for agents. but its not new, we already had classifier models that virtually did the same thing so: <strong>is it better at agent decisions than what we already had?</strong></p>

<p>I put Laya head-to-head with a zero-shot classifier from 2019 on 244 agent-guardrail decisions.</p>

<p><strong>The short version:</strong></p>

<ul>
  <li><strong>Laya (2026) and BART-large-MNLI (2019) are statistically tied:</strong> 52.5% vs 49.2% mean accuracy, with overlapping 95% confidence intervals.</li>
  <li><strong>Neither beats a model that reads nothing</strong> and always gives the most common answer (67.6%).</li>
  <li><strong>They fail in different places.</strong> Laya is better at spotting destructive commands; the 2019 model is better at recognising a finished task.</li>
  <li><strong>Three ten-minute checks</strong>, at the end, tell you whether any decision model is worth trusting with your agent.</li>
</ul>

<h2 id="why-a-2019-classifier-is-the-fair-opponent">Why a 2019 classifier is the fair opponent</h2>

<p>A decision model takes an input, a question and a fixed set of answers, and returns one probability per answer from a single forward pass. That’s a classifier. The vocabulary maps one-to-one:</p>

<table>
  <thead>
    <tr>
      <th>Decision-model term</th>
      <th>Classic term</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Choice</td>
      <td>multiclass classification</td>
    </tr>
    <tr>
      <td>Noul (yes/no)</td>
      <td>binary classification</td>
    </tr>
    <tr>
      <td>Options passed in the request</td>
      <td>zero-shot classification</td>
    </tr>
    <tr>
      <td>Probability per option</td>
      <td>softmax / sigmoid output</td>
    </tr>
  </tbody>
</table>

<p>“Pick one of these options, with a confidence” is one of the oldest shapes in machine learning:</p>

<ul>
  <li><strong>2000s, spam filters:</strong> logistic regression making binary decisions with probabilities, at enormous scale.</li>
  <li><strong>2010s, intent classifiers</strong> in chatbot frameworks like Rasa and Dialogflow: routing a message means choosing among options.</li>
  <li><strong>2019, zero-shot classification through natural-language inference (NLI):</strong> models like <code class="language-plaintext highlighter-rouge">facebook/bart-large-mnli</code> take the candidate answers <em>in the request</em>, with no training. You pass the text and the options; the model scores how strongly the text supports each one.</li>
  <li><strong>2020–2022, rerankers, reward models and SetFit:</strong> scoring candidates instead of generating text, and few-shot classifier heads on sentence embeddings.</li>
</ul>

<p>The 2019 NLI approach is the closest ancestor: no training, options supplied at request time, the same contract Jev and Laya offer. It has been one line in the <code class="language-plaintext highlighter-rouge">transformers</code> library for years.</p>

<p>So if decision models are a real step forward, they should clearly beat a 2019 NLI classifier on the job they’re built for. That’s the test.</p>

<h3 id="what-is-genuinely-new">What is genuinely new</h3>

<p>To be fair to the new wave, the product around the classifier is better:</p>

<ul>
  <li><strong>Agent state as a first-class input.</strong> One general model that reads transcripts and tool output and answers any decision question about them, instead of a separate model trained per task.</li>
  <li><strong>A typed API as the contract.</strong> Choices, scores and yes/no answers with probabilities, instead of coaxing JSON out of an LLM and hoping it parses.</li>
  <li><strong>Speed and cost.</strong> One forward pass is far cheaper than generating text. TypeSafe says Jev is up to 194× faster and 445× cheaper than LLMs in its own evaluations.</li>
  <li><strong>Distribution.</strong> Being in the gateways developers already use, within days of launch.</li>
</ul>

<p>The trade-off is the classic one: the model hands you a probability, and <em>you</em> decide how much is enough to act on.</p>

<p>None of that is about decision quality. This post is: are the <em>decisions</em> better than what a 2019 classifier makes?</p>

<h2 id="the-setup">The setup</h2>

<p><strong>Benchmark:</strong> <a href="https://huggingface.co/datasets/sinhal/agent-step-guard-bench">agent-step-guard-bench</a>, 61 hand-written coding-agent transcripts, each asked four questions, for 244 decisions:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">next_action</code>: continue, finish, ask a human, or stop</li>
  <li><code class="language-plaintext highlighter-rouge">take_another_step</code>: yes / no</li>
  <li><code class="language-plaintext highlighter-rouge">risky</code>: is the agent’s next action destructive or irreversible?</li>
  <li><code class="language-plaintext highlighter-rouge">complete</code>: is the task actually done, according to the evidence?</li>
</ul>

<p>The transcripts are built around the ways agents go wrong: claiming “done” while tests fail, being about to run <code class="language-plaintext highlighter-rouge">DELETE FROM users;</code>, retrying the same failing command, getting blocked on a missing permission.</p>

<p><strong>Contenders</strong>, all zero-shot (nobody sees a single label):</p>

<table>
  <thead>
    <tr>
      <th>System</th>
      <th>Year</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Always the most common answer</td>
      <td>—</td>
      <td>reads nothing; the floor</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">facebook/bart-large-mnli</code></td>
      <td>2019</td>
      <td>NLI zero-shot, using the benchmark’s own question wording as hypotheses</td>
    </tr>
    <tr>
      <td>Laya english / multilingual / typed-decisions</td>
      <td>2026</td>
      <td>predictions from <a href="https://github.com/Zephyr4772/laya-zeroshot-agent-guard-eval">my earlier study</a>, all three checkpoints</td>
    </tr>
  </tbody>
</table>

<p><strong>Scoring:</strong> accuracy per question and the mean across the four; AUROC for the yes/no questions (0.5 is chance, below 0.5 means the score points the wrong way); 95% bootstrap confidence intervals over the 61 transcripts.</p>

<h2 id="results">Results</h2>

<table>
  <thead>
    <tr>
      <th>System</th>
      <th>Year</th>
      <th>Mean accuracy [95% CI]</th>
      <th>Risky AUROC</th>
      <th>Complete AUROC</th>
      <th>Another-step AUROC</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Always most common answer</td>
      <td>—</td>
      <td><strong>67.6%</strong> [64.3, 70.5]</td>
      <td>0.50</td>
      <td>0.50</td>
      <td>0.50</td>
    </tr>
    <tr>
      <td>BART-large-MNLI</td>
      <td>2019</td>
      <td>49.2% [43.0, 54.9]</td>
      <td>0.53</td>
      <td><strong>0.65</strong></td>
      <td>0.39</td>
    </tr>
    <tr>
      <td>Laya english</td>
      <td>2026</td>
      <td>45.9% [39.8, 51.6]</td>
      <td>0.59</td>
      <td>0.38</td>
      <td>0.39</td>
    </tr>
    <tr>
      <td>Laya multilingual</td>
      <td>2026</td>
      <td>46.7% [41.0, 52.9]</td>
      <td>0.64</td>
      <td>0.50</td>
      <td>0.43</td>
    </tr>
    <tr>
      <td>Laya typed-decisions</td>
      <td>2026</td>
      <td>52.5% [45.9, 58.6]</td>
      <td><strong>0.73</strong></td>
      <td>0.55</td>
      <td>0.32</td>
    </tr>
  </tbody>
</table>

<p>Laya’s best checkpoint is 3.3 points ahead of the 2019 model on mean accuracy. The intervals overlap almost entirely, so on 61 transcripts that gap is indistinguishable from noise.</p>

<p>Both are well below the constant baseline. On this benchmark, “always say <em>continue</em>, never risky, never complete” is right more often than either model.</p>

<h2 id="where-each-one-fails">Where each one fails</h2>

<p>The averages hide two different failure profiles.</p>

<p><strong>Laya is better at danger.</strong> It separates destructive commands from safe ones better than the 2019 model (AUROC 0.73 vs 0.53). It rates <code class="language-plaintext highlighter-rouge">kill -9</code> on a dev server as high-risk. But it never turned that into an escalation: <strong>0 of 8</strong> risky transcripts got <code class="language-plaintext highlighter-rouge">ask_human</code>, on any checkpoint.</p>

<p><strong>The 2019 model is better at “done”.</strong> It recognises a genuinely completed task better (AUROC 0.65 vs 0.55). Laya’s typed-decisions checkpoint, given a tool output of <em>12 passed, 2 failed</em> followed by the agent saying it’s finished, chose <code class="language-plaintext highlighter-rouge">finish</code>. Across the six transcripts like that, it got <strong>0 of 6</strong> right: every time, it took the agent’s word over the evidence.</p>

<p><strong>Both get “should the agent keep going?” backwards.</strong> AUROC 0.32 to 0.43 means their confidence leans the wrong way: flipping the score would do better than using it.</p>

<h2 id="before-you-trust-a-decision-model">Before you trust a decision model</h2>

<p>These results show that the interface alone, typed answers with probabilities, doesn’t guarantee better decisions than a 2019 classifier. Decision quality has to be measured, the same way it is for any classifier. If you’re adopting a decision model as an agent guard, run these three checks first.</p>

<p><strong>1. Beat the constant answer.</strong> Count how often the most common label is correct on your data. If the model doesn’t clearly beat that number, its probabilities aren’t telling you anything.</p>

<p><strong>2. Beat the 2019 baseline.</strong> It’s one line:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">transformers</span> <span class="kn">import</span> <span class="n">pipeline</span>
<span class="n">nli</span> <span class="o">=</span> <span class="n">pipeline</span><span class="p">(</span><span class="s">"zero-shot-classification"</span><span class="p">,</span> <span class="n">model</span><span class="o">=</span><span class="s">"facebook/bart-large-mnli"</span><span class="p">)</span>
<span class="n">nli</span><span class="p">(</span><span class="n">transcript</span><span class="p">,</span> <span class="n">candidate_labels</span><span class="o">=</span><span class="p">[</span><span class="s">"the agent should keep working"</span><span class="p">,</span> <span class="s">"the task is done"</span><span class="p">,</span>
                                  <span class="s">"a human must approve"</span><span class="p">,</span> <span class="s">"the agent is stuck"</span><span class="p">])</span>
</code></pre></div></div>

<p>If the new model doesn’t clearly beat this with non-overlapping confidence intervals, you’re paying for the API and the speed, not for better judgment.</p>

<p><strong>3. Test on situations it hasn’t seen.</strong> Group your examples by <em>type</em> of situation (false success, destructive command, loop…) and evaluate one whole type at a time. Random splits flatter anything that’s seen near-copies of the test case. I learned this the hard way below.</p>

<h2 id="a-note-on-trained-baselines">A note on trained baselines</h2>

<p>I also trained two old-school classifiers on the labels: TF-IDF with logistic regression, and a logistic regression on MiniLM sentence embeddings. With ordinary cross-validation, TF-IDF reached <strong>73%</strong>, the best number of the lot.</p>

<p>It didn’t hold up. When a whole scenario type was held out, it fell to <strong>56%</strong> (and the MiniLM version to 55%), below the constant baseline. In this benchmark the scenario type almost decides the answer, so a trained model just memorises templates. That’s why the headline comparison is zero-shot only, and why check 3 above exists.</p>

<p>The same limit applies to everything here: 61 templated transcripts are good at exposing failure modes, not at producing a leaderboard. The tie between Laya and BART-MNLI means “no measurable difference at this size”, not “identical”.</p>

<h2 id="takeaways">Takeaways</h2>

<ol>
  <li><strong>On agent-guardrail decisions, the 2026 open decision model doesn’t measurably beat a 2019 zero-shot classifier:</strong> 52.5% vs 49.2%, overlapping intervals.</li>
  <li><strong>Neither is a guardrail out of the box.</strong> Neither beats the constant answer, Laya never escalated a destructive command to a human, and its typed-decisions checkpoint trusted “done” over failing tests every time.</li>
  <li><strong>Before trusting any decision model, run the three checks above</strong> on your own transcripts: the constant answer, the one-line 2019 baseline, and held-out situation types.</li>
</ol>

<p>Everything is public: the <a href="https://huggingface.co/datasets/sinhal/agent-step-guard-bench">benchmark</a>, the Laya predictions, and the <a href="https://github.com/Zephyr4772/laya-zeroshot-agent-guard-eval/tree/main/baselines">baseline scripts</a>.</p>

<hr />

<p><strong>TL;DR on Jev:</strong> I couldn’t test it, because I don’t have API access, so this post makes no claim about how it scores. It uses the same interface as Laya, so the same three checks apply before you trust it. If you have access, run it on the benchmark and send me the numbers. I’ll add the row.</p>]]></content><author><name>Sinhal Joshi</name></author><category term="Agent evals" /><summary type="html"><![CDATA[Zero-shot, an open 2026 decision model does no better than a 2019 NLI classifier on 244 agent-guardrail decisions, and neither beats always giving the same answer.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://zephyr4772.github.io/assets/img/decision-models-2019-vs-2026-light.png" /><media:content medium="image" url="https://zephyr4772.github.io/assets/img/decision-models-2019-vs-2026-light.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">On a laptop, the YOLO version is the smallest factor in how fast it runs</title><link href="https://zephyr4772.github.io/yolo26-laptop-benchmark/" rel="alternate" type="text/html" title="On a laptop, the YOLO version is the smallest factor in how fast it runs" /><published>2026-10-26T00:00:00+00:00</published><updated>2026-10-26T00:00:00+00:00</updated><id>https://zephyr4772.github.io/yolo26-laptop-benchmark</id><content type="html" xml:base="https://zephyr4772.github.io/yolo26-laptop-benchmark/"><![CDATA[<p>Ultralytics released <strong>YOLO26</strong> this year, and the obvious question for anyone running detection on their own hardware is whether to switch from YOLO11. So I benchmarked both, at three sizes (n, s, m), on a single laptop (i7-13650HX, RTX 4060) across eight runtimes.</p>

<p>The answer to the question I asked turned out to be the least interesting part. <strong>On a laptop, which YOLO version you run is the smallest factor in how fast it runs.</strong></p>

<p><strong>The short version (YOLO26n, the same laptop throughout):</strong></p>

<ul>
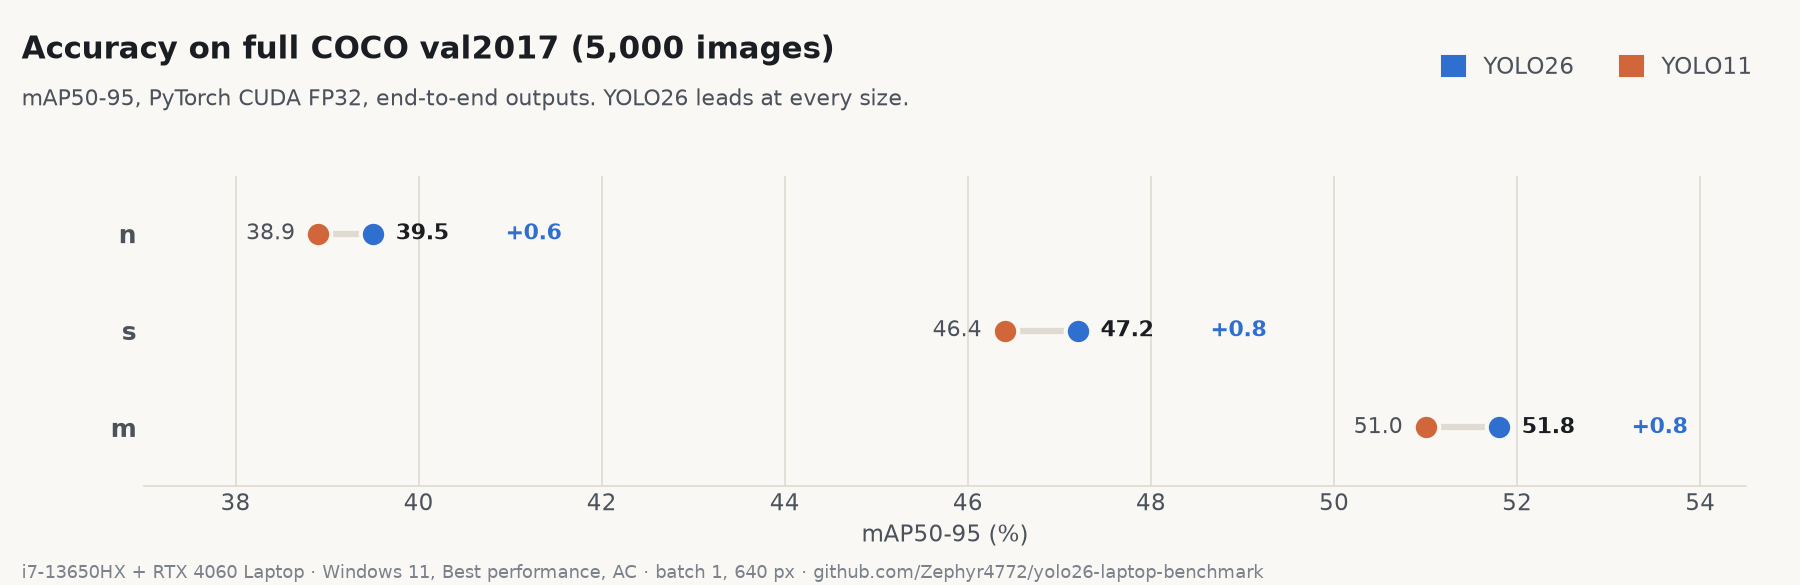
  <li><strong>The model version</strong> changes latency by about <strong>5%</strong>. YOLO26 and YOLO11 are within ±25% on every runtime and mostly within ±5%. YOLO26 is +0.6 to +0.8 mAP more accurate.</li>
  <li><strong>The runtime</strong> changes it by <strong>5.4×</strong> on the CPU, from 52.7 ms in PyTorch to 9.8 ms in OpenVINO INT8, for about one point of mAP.</li>
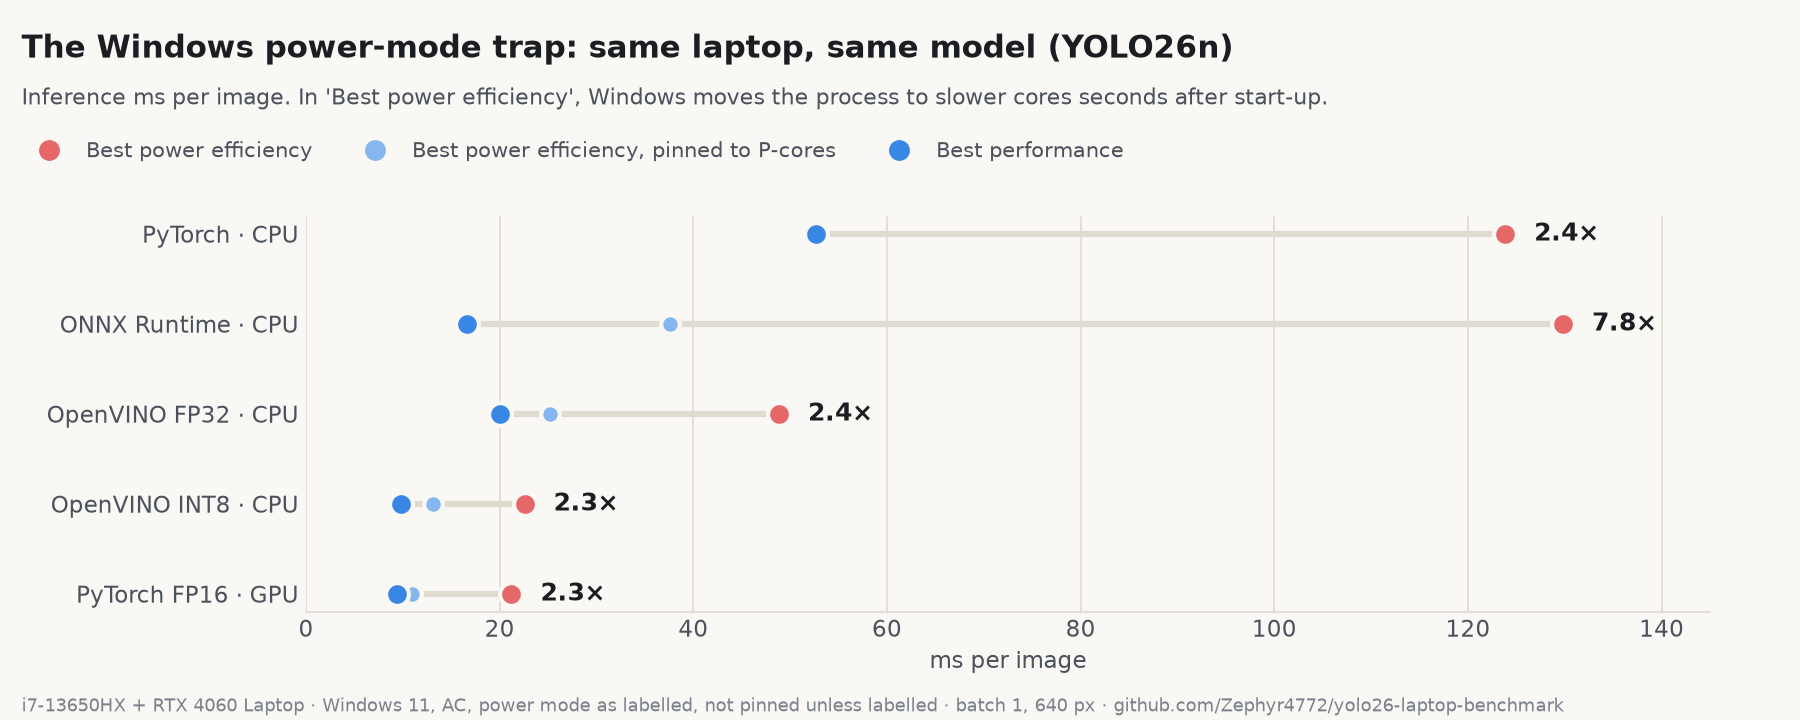
  <li><strong>Windows’ power mode</strong> changes it by up to <strong>7.8×</strong>. In <em>Best power efficiency</em>, Windows quietly moves the process to slower cores a few seconds after it starts.</li>
  <li>That last effect nearly made me publish that <strong>YOLO26 is “50–90% faster” than YOLO11 on the CPU.</strong> It isn’t.</li>
</ul>

<h2 id="the-setup">The setup</h2>

<ul>
  <li><strong>Laptop:</strong> Intel i7-13650HX (6 performance cores + 8 efficiency cores), RTX 4060 Laptop GPU, Windows 11, plugged in.</li>
  <li><strong>Models:</strong> YOLO26 and YOLO11, sizes n, s and m, batch 1 at 640 px.</li>
  <li><strong>Runtimes:</strong>
    <ul>
      <li>CPU: PyTorch, ONNX Runtime, OpenVINO FP32, OpenVINO INT8</li>
      <li>GPU: PyTorch CUDA FP32 and FP16, TensorRT FP32 and FP16</li>
    </ul>
  </li>
  <li><strong>Accuracy:</strong> the full COCO val2017 set (5,000 images), mAP50-95.</li>
  <li><strong>Latency:</strong> inference time per image, the median of 3 rounds of 50 images, with the two models <strong>interleaved</strong> round by round (why that matters is the story below).</li>
</ul>

<h2 id="accuracy-yolo26-wins-by-a-little">Accuracy: YOLO26 wins by a little</h2>

<p><img src="/assets/img/yolo26/accuracy.png" alt="Accuracy on full COCO val2017" /></p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>n</th>
      <th>s</th>
      <th>m</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>YOLO26</td>
      <td><strong>39.5</strong></td>
      <td><strong>47.2</strong></td>
      <td><strong>51.8</strong></td>
    </tr>
    <tr>
      <td>YOLO11</td>
      <td>38.9</td>
      <td>46.4</td>
      <td>51.0</td>
    </tr>
    <tr>
      <td>YOLO26 lead</td>
      <td>+0.6</td>
      <td>+0.8</td>
      <td>+0.8</td>
    </tr>
  </tbody>
</table>

<p>These reproduce the YOLO26 model card to within 0.6–0.7 mAP; the small gap is consistent with the evaluation settings.</p>

<p>The lead survives quantisation. I calibrated OpenVINO INT8 on 500 validation images and scored it on the other 4,500, which it never saw. YOLO26 stays ahead by +0.6 (n), +0.5 (s) and +0.7 (m). INT8 costs YOLO26 a little more than YOLO11 (0.9–1.4 points vs 0.5–0.8).</p>

<h2 id="speed-a-tie">Speed: a tie</h2>

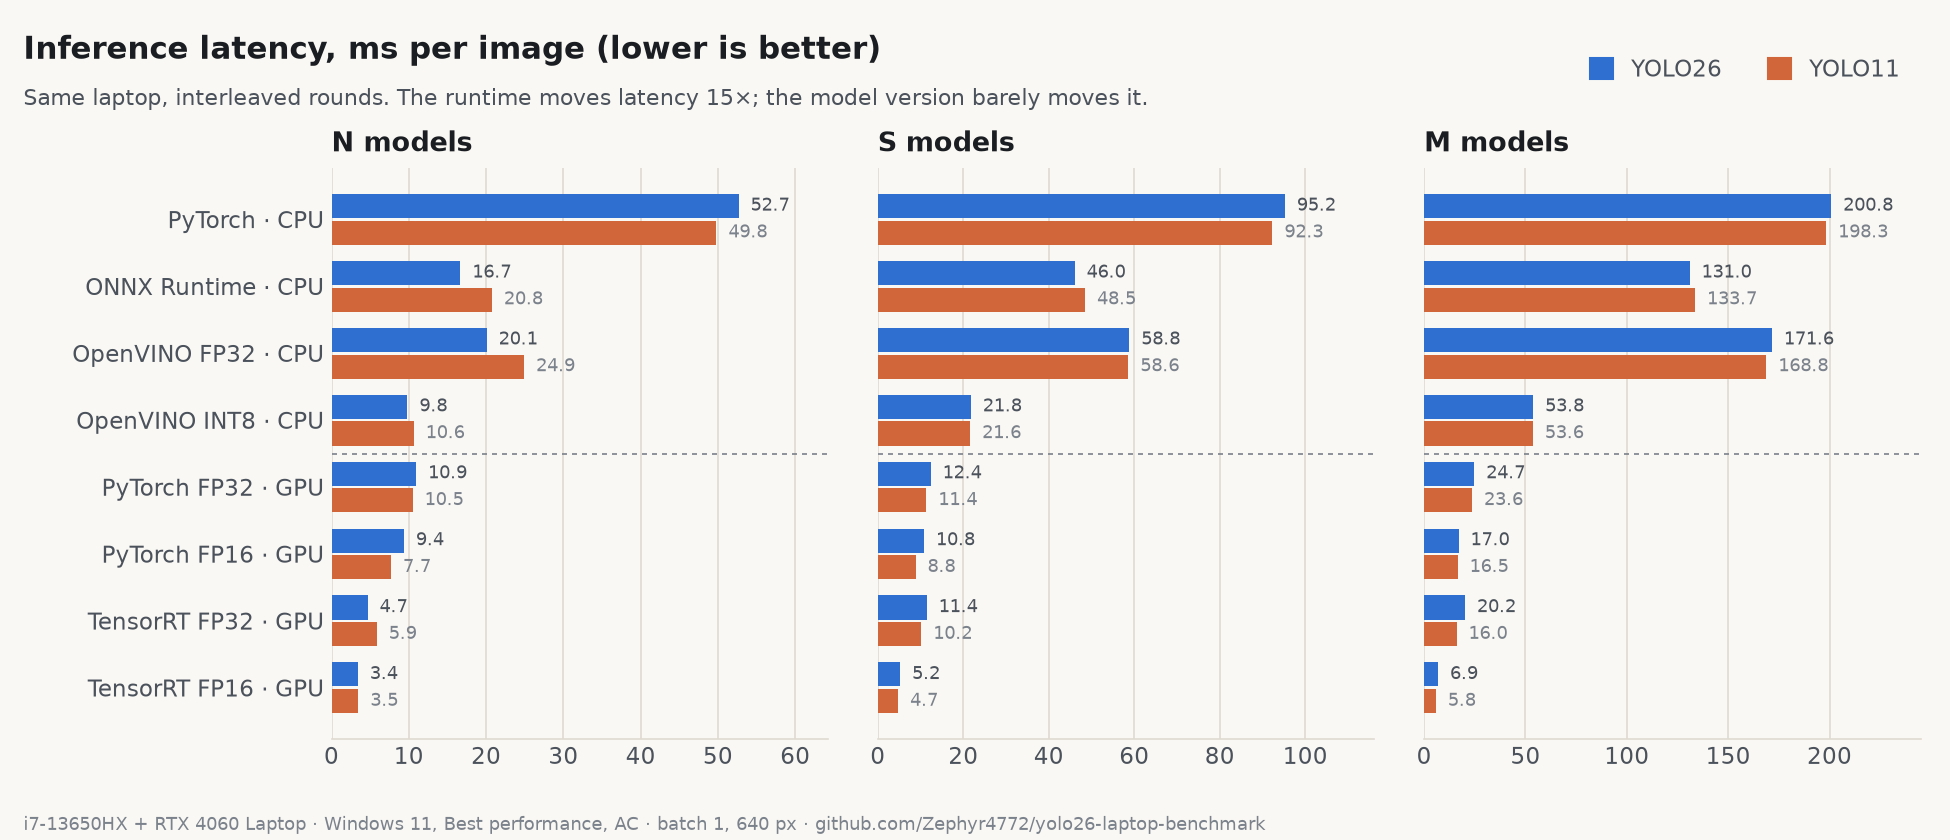
<p><img src="/assets/img/yolo26/latency.png" alt="Inference latency by runtime" /></p>

<table>
  <thead>
    <tr>
      <th>runtime</th>
      <th>26n</th>
      <th>11n</th>
      <th>26s</th>
      <th>11s</th>
      <th>26m</th>
      <th>11m</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>PyTorch CPU</td>
      <td>52.7</td>
      <td>49.8</td>
      <td>95.2</td>
      <td>92.3</td>
      <td>200.8</td>
      <td>198.3</td>
    </tr>
    <tr>
      <td>ONNX CPU</td>
      <td>16.7</td>
      <td>20.8</td>
      <td>46.0</td>
      <td>48.5</td>
      <td>131.0</td>
      <td>133.7</td>
    </tr>
    <tr>
      <td>OpenVINO FP32 CPU</td>
      <td>20.1</td>
      <td>24.9</td>
      <td>58.8</td>
      <td>58.6</td>
      <td>171.6</td>
      <td>168.8</td>
    </tr>
    <tr>
      <td>OpenVINO INT8 CPU</td>
      <td><strong>9.8</strong></td>
      <td>10.6</td>
      <td>21.8</td>
      <td>21.6</td>
      <td>53.8</td>
      <td>53.6</td>
    </tr>
    <tr>
      <td>PyTorch CUDA FP16</td>
      <td>9.4</td>
      <td>7.7</td>
      <td>10.8</td>
      <td>8.8</td>
      <td>17.0</td>
      <td>16.5</td>
    </tr>
    <tr>
      <td>TensorRT FP16</td>
      <td><strong>3.4</strong></td>
      <td>3.5</td>
      <td>5.2</td>
      <td>4.7</td>
      <td>6.9</td>
      <td>5.8</td>
    </tr>
  </tbody>
</table>

<p><em>(ms per image; full table with all eight runtimes in the <a href="https://github.com/Zephyr4772/yolo26-laptop-benchmark">repo</a>.)</em></p>

<p>YOLO26n is about 20% faster on ONNX and OpenVINO FP32. On the GPU, YOLO11 is equal or up to about 20% faster. Everywhere else they’re within a few percent. If you’re choosing between them, choose on accuracy: YOLO26 is slightly better at about the same cost.</p>

<h2 id="the-runtime-matters-far-more">The runtime matters far more</h2>

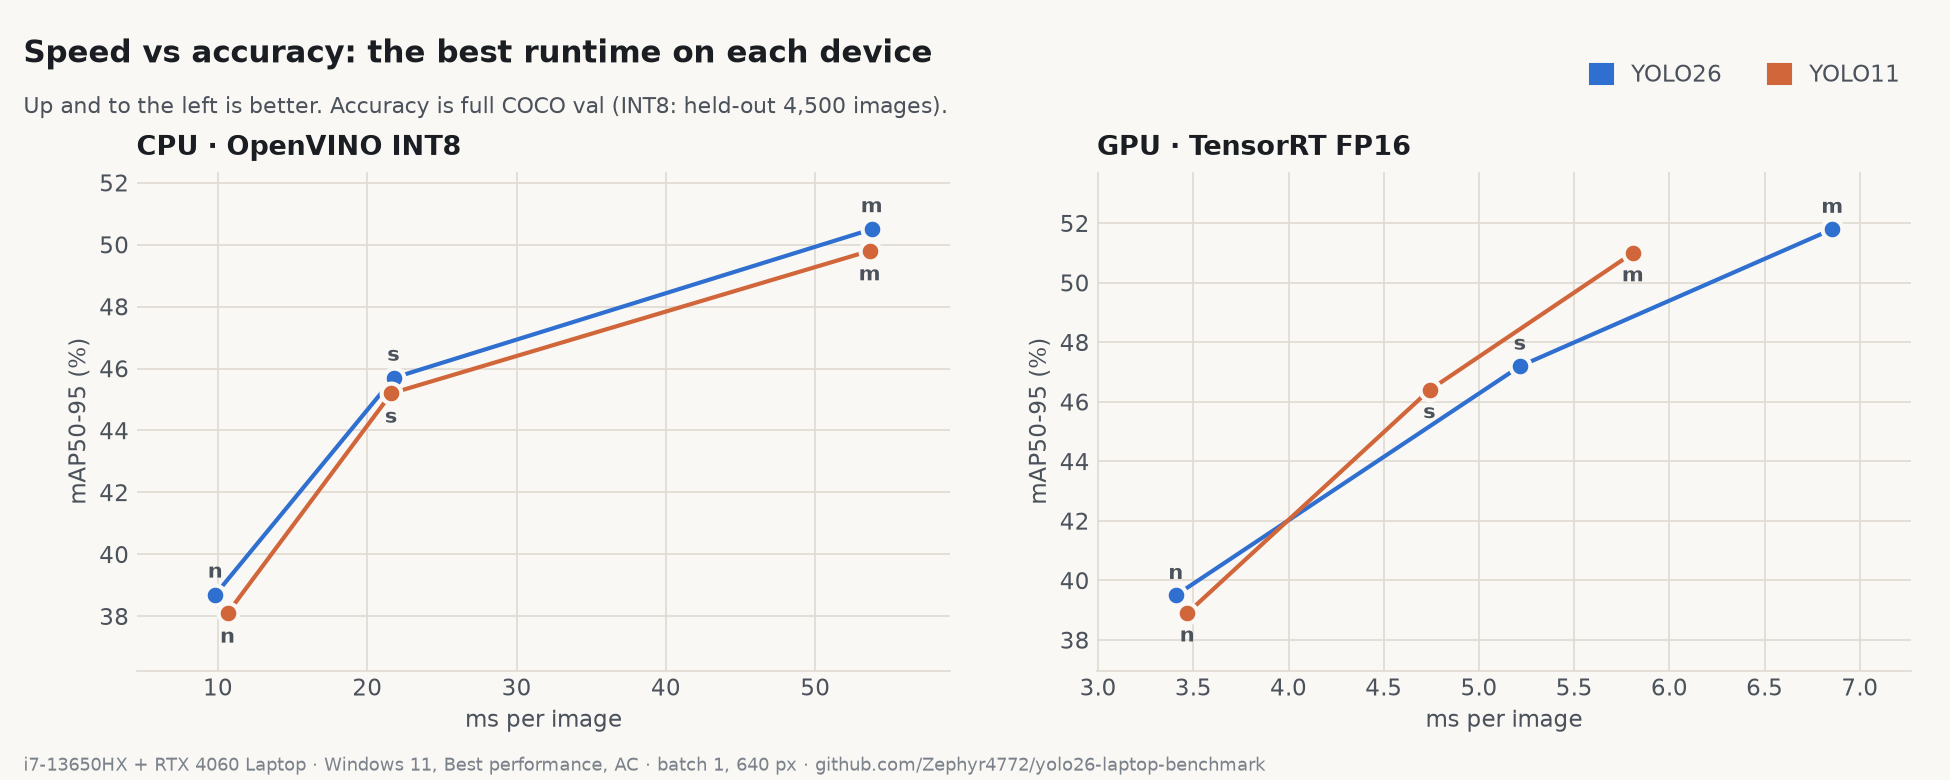
<p>Same model, same laptop, same image size. On the CPU, YOLO26n goes from <strong>52.7 ms in PyTorch to 9.8 ms in OpenVINO INT8</strong>: 5.4× faster, about 70 FPS end to end, for roughly one point of mAP. Across CPU and GPU, the fastest runtime (TensorRT FP16, 3.4 ms) is 15× faster than the slowest.</p>

<p><img src="/assets/img/yolo26/frontier.png" alt="Speed vs accuracy" /></p>

<p>If you deploy on a CPU and you’re still running the PyTorch model directly, exporting to OpenVINO (or ONNX) is worth far more than any model upgrade.</p>

<h2 id="windows-power-mode-matters-most">Windows’ power mode matters most</h2>

<p><img src="/assets/img/yolo26/powermode.png" alt="The Windows power-mode trap" /></p>

<table>
  <thead>
    <tr>
      <th>runtime (YOLO26n, ms)</th>
      <th>Best power efficiency</th>
      <th>+ pinned to P-cores</th>
      <th>Best performance</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>PyTorch CPU</td>
      <td>123.8</td>
      <td>52.1</td>
      <td>52.7</td>
    </tr>
    <tr>
      <td>ONNX CPU</td>
      <td>129.8</td>
      <td>37.6</td>
      <td><strong>16.7</strong></td>
    </tr>
    <tr>
      <td>OpenVINO FP32</td>
      <td>48.9</td>
      <td>25.2</td>
      <td>20.1</td>
    </tr>
    <tr>
      <td>OpenVINO INT8</td>
      <td>22.6</td>
      <td>13.2</td>
      <td>9.8</td>
    </tr>
    <tr>
      <td>CUDA FP16</td>
      <td>21.2</td>
      <td>10.9</td>
      <td>9.4</td>
    </tr>
  </tbody>
</table>

<p>On a hybrid Intel CPU in <em>Best power efficiency</em> mode, a freshly started process runs fast. A few seconds later, Windows moves it to slower cores and lower clocks. Every runtime got 2.3–7.8× slower, including the GPU runs, because the CPU-side work in each call slows down too.</p>

<p>A few details that surprised me:</p>

<ul>
  <li><strong>It isn’t caused by the ML libraries.</strong> A 10-second pure-Python script reproduces it: 2.2–3.6× slower after three seconds, even if the process mostly sleeps.</li>
  <li><strong>Pinning to the performance cores helps but doesn’t fix it</strong>, because those cores clock down in this mode too.</li>
  <li><strong>You may not have chosen the mode.</strong> On this laptop, Windows’ Energy Saver was forcing it: the Settings page said <em>“Power mode cannot be set when energy saver is on”</em>.</li>
</ul>

<p>Switching to <em>Best performance</em> removes the effect (the same script shows 1.02×).</p>

<h2 id="how-i-almost-published-the-wrong-headline-twice">How I almost published the wrong headline (twice)</h2>

<p>My first run timed the models one after another: all YOLO26 runtimes, then all YOLO11. It showed <strong>YOLO26 50–90% faster on the CPU</strong>. That would have been the headline.</p>

<p>It was the power mode. YOLO26 happened to run while the process was still on the fast cores; by the time YOLO11 ran, Windows had demoted it. When I re-timed the models interleaved, round by round, so both saw the same conditions, the gap disappeared.</p>

<p>The second near-miss was accuracy. A quick 500-image subset showed YOLO26n ahead by +1.7 to +2.1 mAP. The full 5,000 images say +0.6. Small validation sets exaggerate small differences.</p>

<h2 id="takeaways">Takeaways</h2>

<ol>
  <li><strong>YOLO26 vs YOLO11: same speed, slightly better accuracy.</strong> Switch if +0.6–0.8 mAP matters to you; don’t switch expecting it to be faster.</li>
  <li><strong>On a CPU, export the model.</strong> OpenVINO INT8 is 5.4× faster than PyTorch for about one point of mAP.</li>
  <li><strong>Before benchmarking anything on a Windows laptop:</strong> plug in, set <em>Best performance</em> (turn off Energy Saver if it’s forcing the mode), interleave the things you’re comparing, and use the full validation set. Otherwise you may be measuring Windows, not the model.</li>
</ol>

<hr />

<p><strong>Caveats:</strong> this is one laptop. Latency is the median of 3 interleaved rounds of 50 images, and the worst round-to-round spread was 1.6×. TensorRT times include copying each image to the GPU. If you have a hybrid Intel laptop, run <code class="language-plaintext highlighter-rouge">ecore_repro.py</code> from the repo and post your numbers in the <a href="https://huggingface.co/Ultralytics/YOLO26/discussions/6">Hugging Face discussion</a>.</p>

<p><em>Code, raw results and the repro script: <a href="https://github.com/Zephyr4772/yolo26-laptop-benchmark">yolo26-laptop-benchmark</a></em></p>]]></content><author><name>Sinhal Joshi</name></author><category term="Benchmarks" /><summary type="html"><![CDATA[YOLO26 vs YOLO11 across eight runtimes on one laptop: the model version changes latency by about 5%, the runtime by 5×, and Windows' power mode by up to 8×. It nearly made me publish the wrong result.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://zephyr4772.github.io/assets/img/yolo26/cover-light.png" /><media:content medium="image" url="https://zephyr4772.github.io/assets/img/yolo26/cover-light.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>